

How Do You Work?
If you’re coding or vibe coding, you’ll have many avenues and levels to manage—with one goal in mind.
To ship—a problem to be solved with this shipped solution.
My problem was running between Notion, Freecamp, and Google Workspace, drowning in tabs and feeling burn out—context switching like crazy.
I got a brilliant idea—it felt smart, lol.
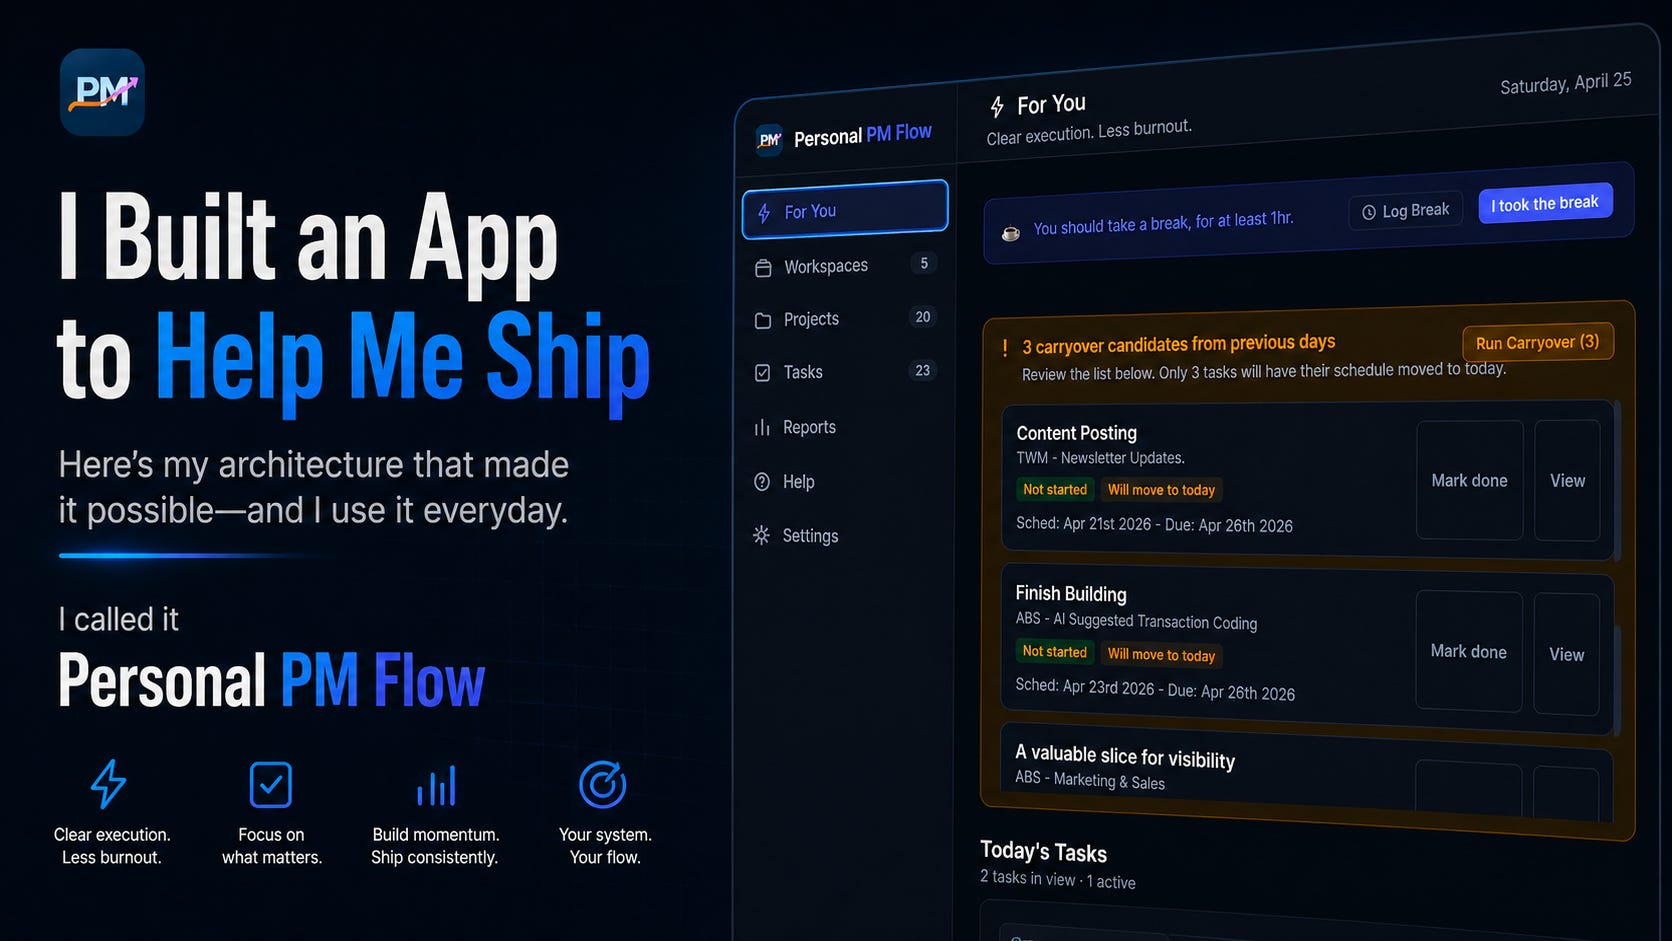
So, I built my own Project/Tasks Management tool to match how I work.
Everyone has a pattern they follow when they execute work—from building, writing, just work—it’s there version of “I have a system for that”
This was my system that came to life in a tool.
What’s up, I’m Clint. Built software. Led teams. Now a founder helping builders who are ready to make the leap but can’t quite see the path yet. Every post is one conversation closer to clarity on ownership, execution and momentum.
I called it Personal PM Flow
This was my first test using Antigravity—Googles answer to Cursor, Codex and Claude.
I described what I needed, and it gave me back something I didn’t ask for—a multi-user, cloud-connected, fully authenticated project management system with role-based access control.
That’s what AI does when you don’t tell it what phase you’re in—it was just scaffolded code and nothing really worked anyways.
It builds for the dream, not the now.
I pushed back—hard.
Then what came out of frustration of back-and-forth, is what built the foundation for what I actually shipped, use every day now.
I learned something that changed how I approach building:
The right architecture for phase 1 is almost never the architecture AI suggests first and how your context is something you MUST manage, not the AI
So, figure I’ll share every major decision, the tradeoff I accepted, and the pitfall I hit along the way.
The How I Work Context Problem
When I described Personal PM Flow to the AI, I said something like:
“I need a project management app to track my tasks, log my time, and help me avoid burnout. I want workspaces, projects, tasks, and a timer.”
What came back: a schema with a users table, JWT auth, a REST API with protected routes, a cloud database connection, and a settings table with user-scoped preferences—it was scoped, but not everything was connected.
All of this is technically correct for an enterprise app but what I needed was something simpler.
AI was building for the product I might want someday, but I really just needed the product that would work this week on my machine, for 1 person—me.
The fix included explaining how I work + why + and expanded prompt—the prompt eventually was built from more back-and-forth and ended up more closer like this:
“I’m a consultant, fractional CTO, forward deploy engineer that sits on client’s team. I need to track my time, and manage my work on 4 levels—workspaces, projects, tasks, & checklist. I’m forced to switch between client work daily, so timer must be seamless transition, I need reporting for my time card. This is local only, single user, no auth needed yet, and most importantly I need this to help me manage my burnout, motivational queues but also a workday limit and barriers to stop. also, I need to use this tomorrow”
The output was now very different and gave me that foundation to what actually shipped.
I started with Antigravity but ended up using that and Claude—this is what created the Which to Use problem.

The Ups and Downs
Here’s what the AI wanted to give me:
[Users] → [Workspaces] → [Projects] → [Tasks]
    ↓           ↓              ↓           ↓
  auth        roles         members    assignees
Here’s what I actually needed:
[Workspace]
    └── [Project] or [Program]
            └── [Task]
                  ├── [Checklist Items]
                  ├── [Time Entries]
                  └── [Recurring Cadence]
I just needed one user, no roles, no assignees.
Just a simple hierarchy, time, and behavior.
It still wasn’t perfect, some early decisions didn’t make it in:
I started with 3 task statuses instead of 2.
AI gave me open and done. I pushed back—I needed deferred.
Because I know myself—I don’t like delete; I’ll almost always archive first and when it came to tasks I hadn’t gotten to. I needed a place to park them.
Pitfall I hit: I didn’t add deferred to the schema until v0.6.0—after I’d already archived a project and watched all its open tasks get marked done when they weren’t.
That was wrong—archive now moves open tasks to deferred, not done.
Behavioral modeling has to come before schema design, not after.
SQLite and Why I Had to Fight for It
AI’s first suggestion was Postgres—always Postgres.
Nothing is wrong with Postgres it’s ok.
But when I said local-first, single user, runs on my laptop—I expected SQLite.
A simple 1 file, no connection pool, no server process, no major configs—my data is literally a file on my machine.
Phase 1 reality:          What AI wanted to give me:
─────────────────         ──────────────────────────
1 user                    Multi-user ready
Local machine             Cloud-hosted
Zero infra                Managed Postgres
Ship this week            "Future-proof" from day 1
My pushback:
“I don’t have concurrent users, I don’t have a server, I have a Mac-Mini. Just give me SQLite.”
SQLite’s synchronous driver can block the event loop under concurrent load and for one person using one app, that never surfaces.
When I’m ready to scale this as a real product with real users, I’ll swap to Postgres—I won’t have to worry about the schema or queries.
Pitfall I hit: No WAL mode enabled on first boot—WAL (Write-Ahead Logging) reduces corruption risk under power failures. I learned this when I asked AI to challenge my implementation details, which allowed me to add it later.
I learned this is something that shouldn’t been skipped as it should have been the first pragma set on database init.
SQLite powers iOS, it powers Android, it powers Firefox, it’s not weak because it says “lite.” For a single-user local app, it’s the right choice for what I was building.
Server Actions vs. REST
The ROADMAP for MVP0 says “API routes.”
So, that’s what I built first but then had to replace it:
REST approach (what I started with):
UI Click → fetch('/api/tasks/start-timer') → API Route → Service → DB → Response → UI update

Server Actions approach (what I ship with):
UI Click → startTimer(taskId) → Server → Service → DB → Page revalidates
By trying to add Server Actions in the beginning but that collapsed the API contract entirely.
There were no endpoint to build, no serialization layer to debug or auth token to pass in.
The function lives on the server and all I had to do is call it from the client locally, then Next.js handles the rest.
For a solo builder with one frontend and no mobile app yet, I think this was a good decision—it’s just moving data around.
If—when—I want a mobile app or external integration, I’ll need to extract a real API.
I deferred that work—it’s in my roadmap at MVP5 and MVP6.
Pitfall I hit: Early on I put business logic directly in the Server Actions instead of a service layer—It felt faster. Can’t test a Server Action in isolation—it was wired to the Next.js runtime. I had to have AI refactor everything into service files.
Do the service layer first, even when it feels like overhead.
The Architecture Layers
┌─────────────────────────────────┐
│         UI Layer                │  Next.js pages, React components
│  (Server Components + Client)   │  Vanilla CSS — no Tailwind
├─────────────────────────────────┤
│       Server Actions            │  Mutations: create, update, delete
│   (app/actions/*.ts)            │  Revalidate the page on completion
├─────────────────────────────────┤
│       Service Layer             │  Business logic — no Next.js here
│   (lib/services/*.ts)           │  TimerService, BurnoutService, etc.
├─────────────────────────────────┤
│       Database Layer            │  SQLite via better-sqlite3
│   (db/index.ts + pmflow.db)     │  Synchronous, local, one file
└─────────────────────────────────┘
Each layer only talks to the layer below it.
UI talks to Actions
Actions talk to Services
Services talk to the DB
Nothing skips a layer, this matters because I vibe coded fast and messy in the beginning—and the errors was ugly.
The layer separation kept it from becoming a pile of dudu. 💩
Now when something breaks, I know exactly which layer to have AI look at.
Pitfall I hit: AI choose Tailwind for CSS, I pushed back. For a solo builder building a personal tool, utility classes add visual noise to a codebase you’re already reading at speed. Vanilla CSS was the best choice here.
Tailwind is great for teams with design systems.
Managing Burnout
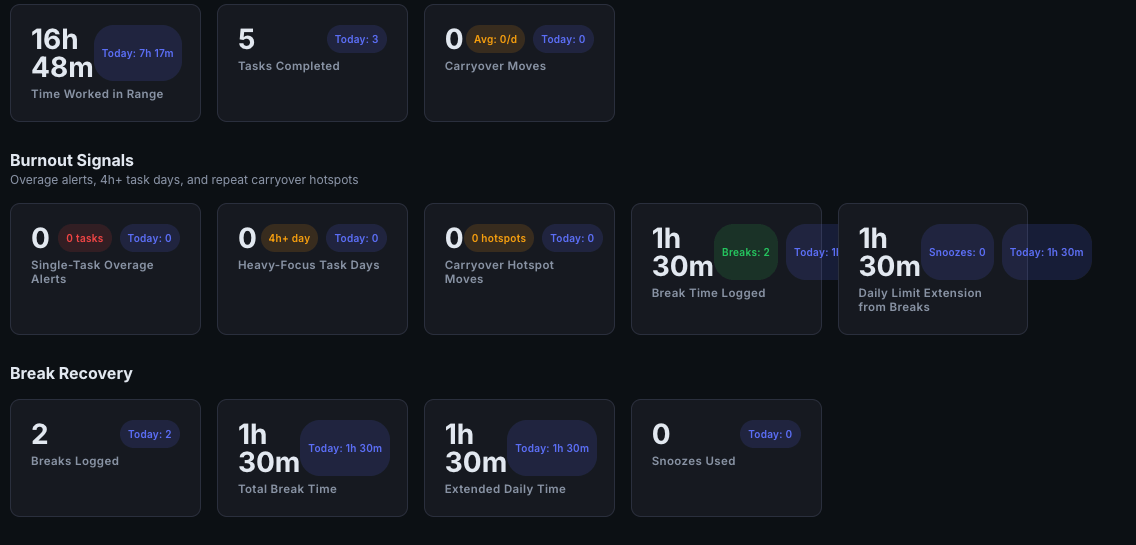
The burnout feature was a late MVP1 addition—it seems that when I first described it to AI, it gave me a frontend-only solution: a JavaScript only timer that tracked hours in the browser, fired an alert and reset on page refresh.
That’s a notification you can ignore by refreshing the page—I wanted it tighter
“This needs to be in the database, I want to know how many times I’ve dismissed the alert to track in a report.”
What AI gave me first:          What I shipped:
──────────────────────          ───────────────
JS counter in browser           burnout_events table in SQLite
Resets on refresh               Persisted forever
No history                      Logs every overage + snooze
No reporting                    Weekly report shows the pattern
The burnout_events table logs every time I hit my daily limit and every time I dismissed it.
When I ran my first weekly report and saw 78 hours, I couldn’t argue with my own database.
That’s different from a notification you can swipe away, right?
Pitfall I hit: The first burnout alert had no escalation at all, it only fired once, you dismissed it, then it was gone. I added a soft alert first, then a hard block. The hard block forces you to pause the timer.
The discipline isn’t in the app—cause the friction is on you.
My CHANGELOG.MD
Most changelogs are for users—maybe teams. Mine is just for me—a record of every time I got something wrong and fixed it.
Here’s some callout of my corrections:
0.6.0 — Archive moves tasks to
deferred, notdone. I got the behavioral model wrong first.0.7.1 — Delete blocked when a child timer is active. I broke data integrity before I added this guard.
0.8.2 — Daily stats now use timezone bucketing. Late-night UTC rows were inflating my “today” hours. Took until 0.8.2 to catch it.
0.8.3 — Focus Mode scope was snapping back to stale project context. Atomic updates fixed it.
Every one of those was a real failure point, it came with frustrations and times feeling stuck.
Now, while using the app daily—if I encounter a potential feature or non-blocking bug—I add it to my backlog and is tracked in changelog when it’s implemented.
The Living Roadmap
MVP0  ✅  Core infrastructure — schema, timer, carryover, reporting
MVP1  ✅  Daily usability — burnout, focus mode, recurring tasks, break logging
MVP2  ⬜  Task & project mobility — duplication, bulk actions
MVP3  ⬜  Reporting intelligence — estimates vs actuals, CSV export
MVP4  ⬜  Notifications — reminders, auto carryover
MVP5  ⬜  Integrations — Google/Outlook calendar (read-only)
MVP6  ⬜  Multi-device — sync, backup + restore UI
A scope contract I made with myself.
When AI suggested building calendar sync in MVP0, I said no—even to AI agent integration.
Every shiny feature that isn’t in the current MVP is in the backlog.
The foundation is clean enough to support all of it.
SQLite becomes Postgres when the user count justifies it.
Server Actions get an API layer when mobile needs it.
But right now, none of that is the constraint—it’s shipped and being used—daily.
I solved my problem of switching between Notion, Freecamp, and Google Workspace, and other tools in my daily work.
"Don't build a better camera; build a better photographer. A small, valuable slice allows the user to achieve a meaningful result immediately, rather than waiting for a perfect machine that never ships." -- Kathy Sierra
The 3 Decisions That Will Always Slow You Down
Choosing your database before you know your user count. SQLite for one. Postgres for many. The mistake is using Postgres for one because you might have many someday. You’re paying a complexity tax on a future that may never arrive.
Building the API before you know your clients. If your only client is a web app you’re building yourself, you don’t need a REST API yet. Server Actions get you to working software faster. The API comes when a second client requirements is mobile, needs integration, or 3-party requirements actually exists.
Letting AI design for scale you don’t have. AI is trained on production systems. It defaults to patterns that handle millions of users, multiple services, and complex auth. When you’re building phase 1 for yourself—or just small—that’s wrong almost every time. The most important thing you can put in your prompt is the constraint: what this does NOT need to do yet.
The Pitfalls That Will Find You Anyway
No WAL mode on SQLite init: add it immediately, not later
Business logic in the wrong layer: it always costs more to move it than to place it right the first time
Behavioral modeling after schema design: know how the app will be used before you design the tables
Over-trusting the first AI response: the first answer is the general answer, not your answer. Push back with your constraints.
Do you have a simple project that AI is making complex?
The builders who ship phase 1 aren’t the ones with the best architecture at all. They’re the ones who learned from the grind of many mistakes, pitfalls and finally land on the right-sized architecture for the problem they’re solving.
The next time AI gives you a multi-user, cloud-connected, fully authenticated system for a personal tool or small tool—I give you permission to push back.
What phase are you in?
Research Notes
Local-First Software: You Own Your Data, In Spite of the Cloud — Ink & Switch (Kleppmann et al., 2019)
Appropriate Uses For SQLite — SQLite.org
Using SQLite in Production — Drifting Ruby
Do Things That Don’t Scale — Paul Graham
Top Five Causes of Scope Creep — Larson & Larson, PMI
Regression Testing Guide — Reflect.run